
Key takeaway
robots.txt controls crawling, noindex controls search indexing, and sitemap.xml lists canonical public URLs. Crawlers must fetch a page to read noindex. Keep local and staging previews non-indexable, and enable production indexing only when domain, HTTPS, env flag, and explicit opt-in align.
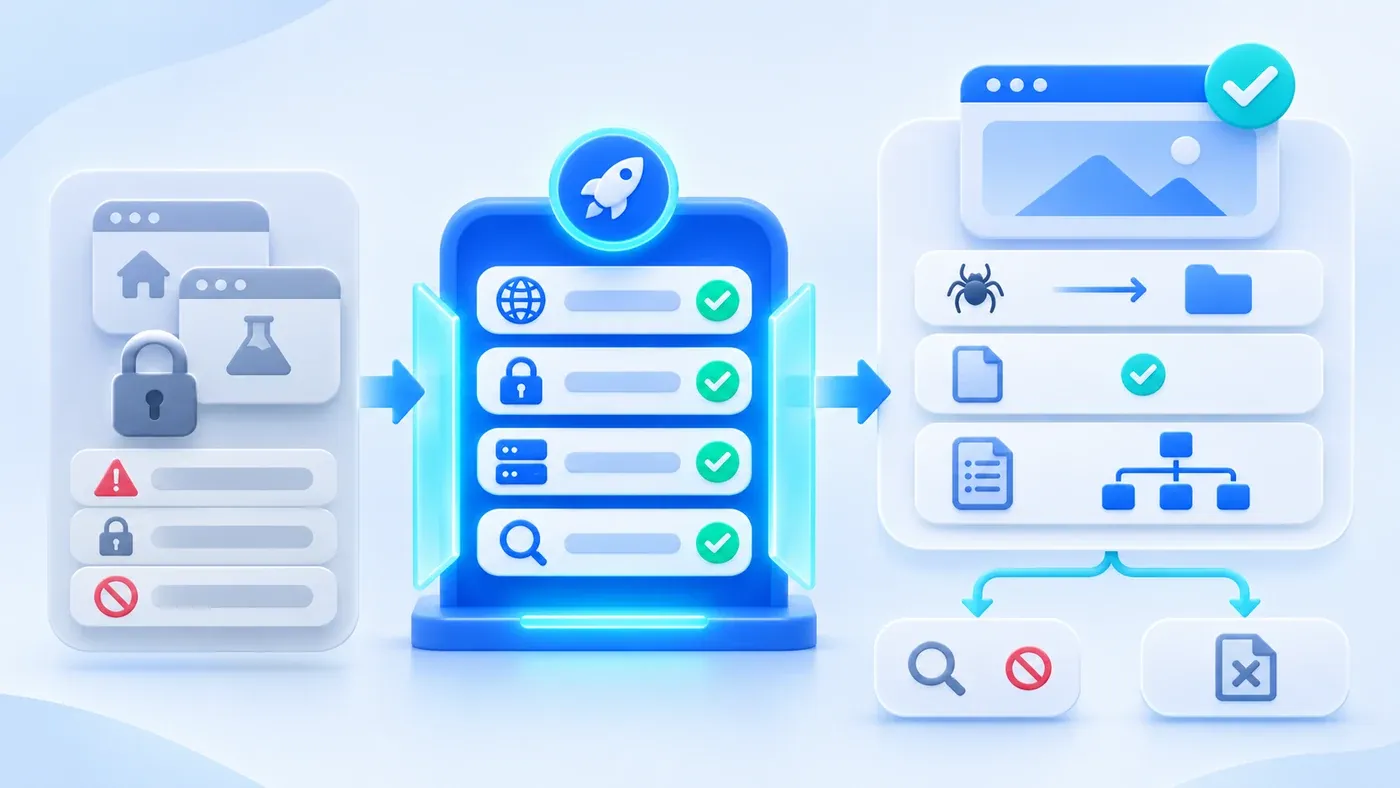
When launching a new website or switching domains after a redesign, costly indexing failures rarely come from layout or copy. They usually trace back to a few lines of crawler and indexing rules. Three mistakes repeat across launches:
- Two weeks post-launch, the site still does not appear for brand searches—because a staging
noindexorDisallow: /rule stayed active in production. - To hide
/admin, previews, or on-site search pages, teams addDisallow:inrobots.txt—and previously indexed URLs remain stuck in search results with no snippet because crawlers cannot fetch the page'snoindexdirective. - Search Console immediately flags
sitemap.xmlerrors—because an export included drafts,/search?q=URLs,404routes, redirects, or staging links.
These failures happen when robots.txt, noindex, and sitemap.xml are treated as interchangeable visibility toggles. Each guards a separate stage: crawling, indexing, and canonical discovery hints. Getting them right sets the technical crawlability baseline noted in SEO and GEO Dual-Track Content Strategy and What Makes Content Easier for AI Search to Cite, without promising instant rankings or guaranteed inclusion.
First Clarify the Roles: What robots.txt, noindex, and sitemap.xml Each Control
- Robots: crawl scope
- Noindex: indexing choice
- Sitemap: canonical discovery
- Authentication: private access
Assess normal collection pagination separately from redundant filters, and keep private content authenticated.
Search engines evaluate crawling and indexing sequentially; misconfiguring an upstream gate blocks downstream instructions.
1. robots.txt Controls Crawling—Not Removal or Security
Per Google Search Central's Introduction to robots.txt, robots.txt manages crawler traffic to avoid overloading servers or crawling low-value paths. Keep three limits clear:
- Disallowing does not guarantee removal: If external pages link to a disallowed URL, Google may still index the URL address without crawling it, displaying no description. Never block JS, CSS, or assets required to render public pages.
- Not a security mechanism: Non-compliant scrapers ignore
robots.txt, and anyone can read/robots.txtto inspect hidden paths. Admin panels and drafts need real server-side authentication. - Bound strictly to host, protocol, and port: Under Google's robots.txt specification guide,
https://www.example.com/robots.txtapplies only to HTTPS onwww.example.com, nothttp://orstaging.subdomains. If/robots.txtreturns4xx(except429), Googlebot treats the host as having no crawl restrictions.
2. noindex Controls Indexing—Only If Crawlers Can Fetch It
Under Google Search Central's guide on blocking indexing with noindex and the Robots meta tag and X-Robots-Tag specification, use <meta name="robots" content="noindex"> in HTML <head> or return X-Robots-Tag: noindex in HTTP headers (ideal for global rules or non-HTML assets like PDFs).
The critical rule: Google ignores noindex inside robots.txt, and crawlers must fetch the URL to see noindex. If an indexed /search?q= or test URL gets both noindex and a robots.txt Disallow:, crawlers never see noindex and the stale URL remains indexed. For already public residual URLs, let crawlers see noindex or a genuine 404/410. Keep authentication on private staging, admin, and drafts; do not expose them merely to request deindexing. Also review links and the relevant search-console records.
3. sitemap.xml Suggests Canonical Public URLs—Not Every Route
Per Google Search Central's guide to building and submitting a sitemap, a sitemap lists canonical public URLs you want crawled and indexed. Use UTF-8 encoding within 50MB and 50,000 URLs at site root, list fully-qualified absolute URLs (https://www.example.com/...), and include only 200-status indexable pages complete in that language. Google ignores <priority> and <changefreq>, reading <lastmod> only when it reliably reflects substantive updates to main content, structured data, or links. Submitting a sitemap is a hint, not a guarantee.
4. Return Genuine HTTP 404 / 410 Status Codes
Per Google's HTTP status code guide, deleted pages without redirects must return real HTTP 404 or 410 rather than a 200 "soft 404"—and must stay unblocked in robots.txt so crawlers detect the status and drop dead URLs.
Isolating Local Previews, Staging, and Production with a Four-Gate Switch
Manual launch-night edits fail easily. Just as critical: never open search indexing on local previews (127.0.0.1, localhost) or test environments. Local previews host drafts and non-public addresses and must remain non-indexable at all times.
One possible deployment policy is a default-closed, four-gate check. Its variables and domain restrictions are project choices, not Google's only eligibility conditions. HTTPS is a secure-deployment recommendation, and a sitemap is a discovery hint; neither guarantees indexing. In this example, open indexing only when all four checks pass:
- Approved live domain: Runtime host matches an official production domain, excluding
localhost,127.0.0.1, IPs, andstaging.hosts. - Public HTTPS: Traffic serves over
https://so canonicals,robots.txt, andsitemap.xmlnever leakhttp://. - Production env flag: Config explicitly indicates production (e.g.,
WEBSITE_ENV=production), lockinglocalandstaging. - Explicit indexing opt-in: A dedicated toggle enables indexing (e.g.,
WEBSITE_INDEXING=enabled), defaulting to disabled when omitted.
Even when all four gates are open, route-level rules always win: admin and draft previews remain authenticated and non-indexable. Public search or pages marked noIndex may use noindex without universally requiring nofollow; omit non-indexable URLs from the submitted production sitemap. Lock public staging behind password or IP allowlists first, or send global X-Robots-Tag: noindex, nofollow with no sitemap during unauthenticated review.
On a ready production host, keep /robots.txt concise (illustrative domain):
User-agent: *
Disallow: /admin/
Sitemap: https://www.example.com/sitemap.xml
And list only canonical 200 HTTPS URLs in /sitemap.xml:
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://www.example.com/en/services/website</loc>
    <lastmod>2026-11-16</lastmod>
  </url>
</urlset>
If Chinese and English sites use separate domains, serve an independent /robots.txt and /sitemap.xml on each root host while aligning canonical and hreflang separately.
Reference Matrix: robots.txt, noindex, and sitemap.xml Across Five Website Page Types
Website Page Category | | | Include in | Rationale & Common Pitfall |
|---|---|---|---|---|
Core Public Pages (Home, Services, Solutions, Projects, Insights) | Allow crawling (including JS/CSS/media) | HTTP | Yes (published, locale-ready canonical URLs only) | Enables rendering and indexing; watch for leftover staging |
On-Site Search & Redundant Filter Variants ( | Keep accessible when relying on | Usually | Omit URLs not intended for indexing | Follow Google pagination guidance to distinguish ordinary paginated content from redundant query variants, and make removal signals readable on public residual URLs. |
Draft Previews & Admin ( | Optional | Enforce login auth ( | No | |
Test & Local Previews ( | Never index locally; gate public staging by auth/VPN | Global | No (never submit test-host sitemaps) | Keeps test clones out of search; keep private staging authenticated even when removing previously indexed URLs. |
404 & Retired Pages (Unknown or deleted URLs) | Do not block in | Return true HTTP | No | Crawlers must fetch |
10-Minute Pre-Launch Indexing Verification Checklist
Run these checks right before and after DNS cutover:
[10-Minute Website Launch Indexing Verification Checklist]

1. Local & Staging Lock (Pre-Cutover)
- [ ] Confirm local previews (127.0.0.1 / localhost) remain non-indexable with global noindex intact.
- [ ] Confirm public staging enforces auth/IP rules or X-Robots-Tag: noindex, nofollow, with zero links from production.

2. Production Four-Gate Switch (At Cutover)
- [ ] Verify all four gates hold: production domain + public HTTPS + production env flag + explicit indexing opt-in.
- [ ] Check Chinese and English domains separately if hosted on distinct hosts.

3. Live /robots.txt Check (Post-Cutover)
- [ ] Fetch https://<production-domain>/robots.txt: HTTP 200, no Disallow: /, JS/CSS crawlable.
- [ ] Confirm Sitemap: points to full https:// production sitemap with no localhost or staging hosts.

4. Positive & Negative noindex Checks (HTML & Headers)
- [ ] Home, Service page, and Article: zero noindex in <meta> or X-Robots-Tag.
- [ ] /en/search?q=test and /zh/search?q=test: noindex present and not blocked by robots.txt.
- [ ] Incognito /admin and draft preview URL: login gate enforced plus noindex, nofollow.

5. /sitemap.xml Audit
- [ ] Open https://<production-domain>/sitemap.xml: HTTP 200, UTF-8 XML, absolute https:// URLs.
- [ ] Spot-check <loc>: published, locale-ready pages only; zero /search, /admin, redirects, or 404s.

6. 404 & Redirect Check
- [ ] Request a missing path (e.g., /en/check-nonexistent-404): verify HTTP 404, not 200.
- [ ] Spot-check legacy redirects for single-hop 301/308 targets.

7. Search Console Registration
- [ ] Verify production domain in Google Search Console (and target tools), submit sitemap.xml, and run URL Inspection.
Coordinating robots.txt, noindex, HTTP status codes, and sitemap.xml helps expose launch configuration mistakes. Pair this with our Website Project Preparation Checklist to inventory existing URLs, or explore our Corporate Website & Standalone Site Services to review your launch setup together.
Sources
- Google Search Central: Introduction to robots.txt ↗
- Google Search Central: Block Search indexing with noindex ↗
- Google Search Central: Build and submit a sitemap ↗
- Google Search Central: Robots meta tag, data-nosnippet, and X-Robots-Tag specifications ↗
- Google Search Central: How HTTP status codes affect Google's crawlers ↗
- Google Search Central: How Google interprets the robots.txt specification ↗
- Google: Pagination and incremental page loading ↗
